
After getting to know the OpenObserve and its unified platform for logs, metrics, and traces, the next step is to operate it on a dedicated Ubuntu server without Docker. This guide installs the official binary as a service systemd, keeps the OpenObserve port on loopback, publishes the interface via nginx with TLS, and shows when to use local disk or S3, Google Cloud Storage, Oracle Cloud Object Storage, and MinIO.
Technical review: 7 October 2026. Recipe for a fresh install with sudo on Ubuntu and Bash. Choose disk or bucket before the first ingestion. Providers are alternatives, not cumulative steps; do not run as a migration over an existing instance.
Architecture and sizing
| Scenario | Metadata | Telemetry data | When to use |
|---|---|---|---|
| Dedicated server with disk | Local SQLite | Local disk in Parquet | Small or medium environment, simple operation and limited retention. |
| Small server + object storage | Local SQLite | S3, GCS, Oracle Object Storage or MinIO | When capacity and durability must exceed the VM disk. |
| High availability | PostgreSQL | Object storage | Critical service, horizontal scaling, and fault tolerance. |
Local mode is the default: uses SQLite for metadata and can write stream data to disk or S3-compatible storage. For a single-node bucket, set ZO_LOCAL_MODE_STORAGE=s3. Do not change the backend of an instance with data without a migration plan, backup, and restore test: pointing to a bucket does not automatically migrate existing Parquet files.
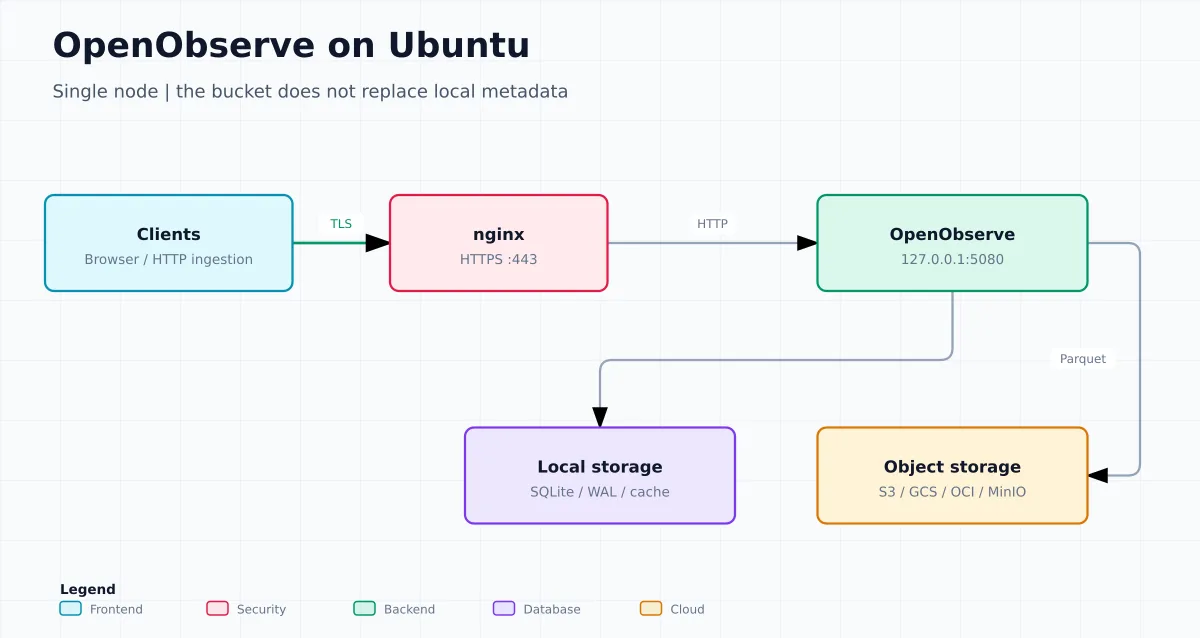
Bucket does not turn a single node into HA. SQLite and in-progress ingestion data remain local. Losing these components may prevent full recovery, even if already uploaded objects remain in the bucket. On the disk option, Parquet also stays local. See the official architecture.
Scale with a representative pilot: daily growth, retention, ingestion peak, query concurrency, CPU, memory, and I/O. Reserve space for WAL, cache, and compaction, and measure recovery after failures. There is no universal correspondence between stored terabytes and vCPUs. Monitor free bytes and inodes; RAID does not replace backup.
1. Prepare Ubuntu and create the service user
Update the system and install only utilities used to download, validate, and extract the archive. The OpenObserve process runs under a system account without login; the binary remains under root control and data is located in /var/lib/openobserve.
sudo apt update
sudo apt install -y ca-certificates curl openssl tar

sudo adduser --system --group --home /var/lib/openobserve \
  --shell /usr/sbin/nologin openobserve
sudo install -d -o root -g root -m 0755 /usr/local/lib/openobserve
sudo install -d -o openobserve -g openobserve -m 0750 /var/lib/openobserve
sudo install -d -o root -g openobserve -m 0750 /etc/openobserve
Do not use an administrative shell account for the service. Separation allows limiting who reads credentials and who writes to local data.
2. Download and install the official binary
First consult the official downloads page and replace OO_VERSION with a stable release that you have qualified for production. The example uses v1.0.4, stable release checked on 7 October 2026, without promising that it will be the latest in the future. It detects amd64 or arm64; for machines with old glibc, the documentation recommends using the package linux-amd64-musl, with possible performance cost.
Select the Open Source edition in the downloads; Enterprise artifacts have different names. Run the block in Bash. On the Downloads page, select Open Source, the version, and the architecture; use the Show SHA256 button for the corresponding package. The hash must be the one published by the vendor for that artifact.
(
set -euo pipefail
export OO_VERSION=v1.0.4
case "$(dpkg --print-architecture)" in
  amd64|arm64) OO_ARCH="$(dpkg --print-architecture)" ;;
  *) echo "Arquitetura não suportada"; exit 1 ;;
esac

OO_TARBALL="openobserve-${OO_VERSION}-linux-${OO_ARCH}.tar.gz"
OO_URL="https://downloads.openobserve.ai/releases/openobserve/${OO_VERSION}/${OO_TARBALL}"

WORK=$(mktemp -d)
trap 'rm -rf -- "$WORK"' EXIT
cd "$WORK"
curl -fL -o "$OO_TARBALL" "$OO_URL"
read -r -p "SHA-256 oficial desse arquivo: " EXPECTED
[[ "$EXPECTED" =~ ^[[:xdigit:]]{64}$ ]] || { echo "Hash inválido"; exit 1; }
printf '%s  %s\n' "$EXPECTED" "$OO_TARBALL" | sha256sum --check -

mkdir "$WORK/unpack"
tar -xzf "$OO_TARBALL" -C "$WORK/unpack"
sudo install -o root -g root -m 0755 \
  "$WORK/unpack"/openobserve \
  "/usr/local/lib/openobserve/openobserve-${OO_VERSION}"
sudo ln -sfn "/usr/local/lib/openobserve/openobserve-${OO_VERSION}" \
  /usr/local/bin/openobserve

/usr/local/bin/openobserve --version
)
The checksum is a mandatory step before executing a downloaded binary. Keep the installed version: updates should download a new release, validate the hash, install a different file, and only then swap the symbolic link during a maintenance window.
3. Create the environment file
OpenObserve is configured via environment variables. Create a file that only root and the service group can read. The root password is used on first initialization; generate a long password, save it to a vault, and replace the example values before starting the service.
sudo install -o root -g openobserve -m 0640 /dev/null /etc/openobserve/openobserve.env
sudo tee /etc/openobserve/openobserve.env > /dev/null <<'EOF'
ZO_ROOT_USER_EMAIL=admin@example.com
ZO_ROOT_USER_PASSWORD=TROQUE_POR_UMA_SENHA_LONGA_E_ALEATORIA

# Nó único, dados no disco local
ZO_LOCAL_MODE=true
ZO_LOCAL_MODE_STORAGE=disk
ZO_DATA_DIR=/var/lib/openobserve

# O nginx será a única entrada pública
ZO_HTTP_ADDR=127.0.0.1
ZO_HTTP_PORT=5080
ZO_GRPC_ADDR=127.0.0.1
ZO_WEB_URL=https://o2.exemplo.com
ZO_CORS_ALLOWED_ORIGINS=https://o2.exemplo.com

# Ajuste a retenção ao piloto e ao espaço disponível
ZO_COMPACT_DATA_RETENTION_DAYS=30
EOF
sudo chown root:openobserve /etc/openobserve/openobserve.env
sudo chmod 0640 /etc/openobserve/openobserve.env

# Gere uma senha para copiar ao cofre; depois cole-a no arquivo acima.
openssl rand -hex 32
sudoedit /etc/openobserve/openobserve.env
ZO_HTTP_ADDR=127.0.0.1 avoids publishing port 5080 directly. We also define ZO_GRPC_ADDR=127.0.0.1 so the default gRPC port isn't exposed on the network. If OpenObserve is served on a subpath, like https://exemplo.com/logs/, use ZO_BASE_URI=/logs and adjust the proxy.
Do not start with the example password. Replace password and domain with sudoedit; for bucket, now apply the block from section 6. The file creation command is for a new installation: do not repeat it over the existing configuration.
4. Run as systemd service
Create the unit. The file descriptor limit follows the official guide's recommendation; Restart=on-failure it tries to recover from failures, but it does not fix invalid configuration; monitor logs and the restart limit.
sudo tee /etc/systemd/system/openobserve.service > /dev/null <<'EOF'
[Unit]
Description=OpenObserve
After=network-online.target
Wants=network-online.target

[Service]
Type=simple
User=openobserve
Group=openobserve
WorkingDirectory=/var/lib/openobserve
EnvironmentFile=/etc/openobserve/openobserve.env
ExecStart=/usr/local/bin/openobserve
ExecStop=/bin/kill -s QUIT $MAINPID
Restart=on-failure
RestartSec=5
LimitNOFILE=65535
NoNewPrivileges=true
PrivateTmp=true
ProtectHome=true

[Install]
WantedBy=multi-user.target
EOF

sudo systemctl daemon-reload
sudo systemctl enable --now openobserve
sudo systemctl status openobserve --no-pager
curl -fsS http://127.0.0.1:5080/healthz; echo
sudo journalctl -u openobserve -n 100 --no-pager
The expected response from the health check is {"status":"ok"}. If the service doesn't start, confirm permissions in /var/lib/openobserve, the environment file syntax and the log of the journalctl. Do not change the root password on an already-initialized instance hoping to recreate the user: these variables are only needed on the first start.
5. Install nginx and publish with TLS
After validating OpenObserve on loopback, publish it with its own DNS name, for example o2.exemplo.com. Before requesting the certificate, create A records (and AAAA if using IPv6) pointing to the server and confirm that ports 80 and 443 reach it. OpenObserve stays on 127.0.0.1:5080; only nginx will be exposed.
Install the reverse proxy
sudo apt update
sudo apt install -y nginx certbot python3-certbot-nginx
sudo systemctl enable --now nginx
sudo nginx -t
sudo systemctl status nginx --no-pager
If the host uses UFW, first preserve administrative access and allow only HTTP/HTTPS. In cloud providers, make the same release in the provider's firewall or security group.
# Execute somente se UFW já faz parte da política deste host.
sudo ufw allow OpenSSH  # somente se o SSH usa o perfil/porta padrão
sudo ufw allow 'Nginx Full'
sudo ufw status verbose
First create an HTTP virtual host. It deliberately returns 404 and does not serve the application over HTTP; Certbot will configure the HTTP-01 challenge from Let’s Encrypt. Do not expose port 5080 or 5081 on the firewall.
sudo tee /etc/nginx/sites-available/openobserve >/dev/null <<'EOF'
server {
    listen 80;
    listen [::]:80;
    server_name o2.exemplo.com;

    location / {
        return 404;
    }
}
EOF

sudo ln -s /etc/nginx/sites-available/openobserve /etc/nginx/sites-enabled/openobserve
sudo nginx -t
sudo systemctl reload nginx
curl -sSI http://o2.exemplo.com/
Use a subdomain, as in the example. If you choose to publish under a path, like https://exemplo.com/logs/, follow the OpenObserve documentation and define ZO_BASE_URI=/logs; just adding location /logs/ in nginx is not sufficient.
Issue and renew the certificate
With DNS propagated and port 80 publicly accessible, Certbot's nginx plugin can obtain the certificate and install the HTTPS block. Make a backup of the configuration before letting Certbot modify it.
sudo cp -a /etc/nginx /etc/nginx.backup.$(date +%F)
sudo certbot --nginx --redirect -d o2.exemplo.com
sudo nginx -t
sudo systemctl reload nginx
sudo certbot renew --dry-run
curl -sSI https://o2.exemplo.com/
Enable the proxy only on the HTTPS block
Edit /etc/nginx/sites-available/openobserve. In the block 443 created by Certbot, replace only the location / that returns 404 with the block below. Preserve the TLS directives and keep port 80 with redirection and renewal.
location / {
    client_max_body_size 20m;
    proxy_pass http://127.0.0.1:5080;
    proxy_http_version 1.1;
    proxy_set_header Host $host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;
    proxy_set_header X-Envoy-External-Address "";
    proxy_buffering off;
    proxy_read_timeout 300s;
}
The values 20m and 300s are initial choices for this recipe, not universal ones. Batches above the body limit receive 413: adjust the collector before raising the limit indiscriminately. Disabling buffering avoids backing up stream responses. The example assumes clients reaching nginx directly, with no other proxy in front.
sudo nginx -t && sudo systemctl reload nginx
curl --fail --silent --show-error https://o2.exemplo.com/healthz
Body limit and proxy directives in the nginx documentation.
The --redirect redirects HTTP to HTTPS. The test renew --dry-run confirms renewal before the expiration date. For corporate certificates or DNS-01 validation, don't run the above command: install the certificate according to organizational policy and keep the same proxy for 127.0.0.1:5080.
ss -lntp | grep -E ':(80|443|5080|5081)\b'The result should show nginx at 80/443 and OpenObserve ports 5080 and 5081 only on loopback, never in 0.0.0.0. Do not expose the interface, ingestion APIs, or the MCP endpoint over plain HTTP.
Validate ingestion and query before real data
If you chose bucket, first complete the 6 section; only then send the event. Health check does not prove ingestion. Use the JSON event and the SQL query from introductory tutorial, replacing the URL with https://o2.exemplo.com and the user with the created account. Confirm the event, restart the service, and query again.
The proxy shown serves HTTP, it does not publish OTLP/gRPC on 5081. Configure the exporter to the proper protocol and endpoint; do not open 5081 just because it uses gRPC by default.
6. Use S3, GCS, Oracle Cloud or MinIO
Configure the backend before the first ingestion. In an existing instance, changing variables does not migrate the data. With object storage, SQLite and WAL remain on the local disk. Edit the same file /etc/openobserve/openobserve.env, change ZO_LOCAL_MODE_STORAGE to s3, add a provider block and restart the service. Create the bucket first, use a unique prefix per environment, and test writing, reading, and retention in a staging environment.
AWS S3
On EC2, prefer an IAM Role with minimal access to the bucket and prefix instead of static credentials. For standard S3, do not set ZO_S3_SERVER_URL; the SDK looks up the instance identity. Outside of AWS, inject the keys via a secrets manager or the environment file with permission 0640; never include them in Git.
# Em EC2 com IAM Role: não defina AWS_ACCESS_KEY_ID nem AWS_SECRET_ACCESS_KEY
ZO_LOCAL_MODE_STORAGE=s3
ZO_S3_PROVIDER=s3
ZO_S3_REGION_NAME=us-east-1
ZO_S3_BUCKET_NAME=openobserve-producao
ZO_S3_BUCKET_PREFIX=openobserve/producao/
# Fora da AWS: entregue estes valores por cofre de segredos
AWS_ACCESS_KEY_ID=CHAVE_DE_ACESSO
AWS_SECRET_ACCESS_KEY=SEGREDO_DE_ACESSO
ZO_LOCAL_MODE_STORAGE=s3
ZO_S3_PROVIDER=s3
ZO_S3_REGION_NAME=us-east-1
ZO_S3_BUCKET_NAME=openobserve-producao
ZO_S3_BUCKET_PREFIX=openobserve/producao/Google Cloud Storage
GCS can use the S3-compatible API. Create an HMAC key with restricted access to the bucket and use HTTP/1, as required by the documented configuration:
ZO_LOCAL_MODE_STORAGE=s3
ZO_S3_SERVER_URL=https://storage.googleapis.com
ZO_S3_REGION_NAME=auto
ZO_S3_ACCESS_KEY=CHAVE_HMAC_GCS
ZO_S3_SECRET_KEY=SEGREDO_HMAC_GCS
ZO_S3_BUCKET_NAME=openobserve-producao
ZO_S3_BUCKET_PREFIX=openobserve/producao/
ZO_S3_FEATURE_HTTP1_ONLY=true
ZO_S3_PROVIDER=s3
Direct integration also exists: use ZO_S3_PROVIDER=gcs and, when there is no instance identity, provide in ZO_S3_ACCESS_KEY the path to the service account JSON key, with read-only permission for the user openobserve.
Oracle Cloud Object Storage
Oracle Object Storage offers an S3-compatible API. Use a Customer Secret Key, keep the URL in your tenancy and region format, and validate the configuration in a test bucket before writing production data.
ZO_LOCAL_MODE_STORAGE=s3
ZO_S3_SERVER_URL=https://SEU_NAMESPACE.compat.objectstorage.SUA_REGIAO.oci.customer-oci.com
ZO_S3_REGION_NAME=SUA_REGIAO
ZO_S3_ACCESS_KEY=OCI_ACCESS_KEY
ZO_S3_SECRET_KEY=OCI_CUSTOMER_SECRET_KEY
ZO_S3_BUCKET_NAME=openobserve-producao
ZO_S3_BUCKET_PREFIX=openobserve/producao/
ZO_S3_PROVIDER=s3
ZO_S3_FEATURE_FORCE_HOSTED_STYLE=false
MinIO
MinIO is an S3-compatible option for datacenter, another VM, or Kubernetes. Create the bucket before starting and use TLS between OpenObserve and the endpoint. A MinIO on the same host does not create redundancy: a machine failure can take down both application and data at the same time.
ZO_LOCAL_MODE_STORAGE=s3
ZO_S3_SERVER_URL=https://minio.exemplo.com
ZO_S3_REGION_NAME=us-east-1
ZO_S3_ACCESS_KEY=MINIO_ACCESS_KEY
ZO_S3_SECRET_KEY=MINIO_SECRET_KEY
ZO_S3_BUCKET_NAME=openobserve-producao
ZO_S3_BUCKET_PREFIX=openobserve/producao/
ZO_S3_PROVIDER=minio
sudoedit /etc/openobserve/openobserve.env
sudo systemctl restart openobserve
sudo journalctl -u openobserve -fRustFS as an S3-compatible target
The current documentation also describes RustFS as a destination. Use the HTTPS endpoint of the S3 API, not the console; create the bucket and application credential first:
ZO_LOCAL_MODE_STORAGE=s3
ZO_S3_PROVIDER=s3
ZO_S3_SERVER_URL=https://s3.exemplo.com
ZO_S3_REGION_NAME=us-east-1
ZO_S3_ACCESS_KEY=CHAVE_DA_APLICACAO
ZO_S3_SECRET_KEY=SEGREDO_DA_APLICACAO
ZO_S3_BUCKET_NAME=openobserve-producao
ZO_S3_BUCKET_PREFIX=openobserve/producao/
ZO_S3_FEATURE_FORCE_HOSTED_STYLE=false
Validate write, read, restart, and retention; this review did not run integration against that backend. Authorize the required bucket/prefix, including delete operations used by retention. Official backend reference.
7. Integrate AI agents and LLM applications
Yes: OpenObserve can participate in an LLM flow in two ways. The first is observing the AI application via OpenTelemetry — tokens, latency, model, errors, and tool calls become traces and metrics. The second is connecting an MCP client to query logs, metrics, and traces in natural language.
The MCP endpoint follows the format https://o2.exemplo.com/api/ID_DA_ORGANIZACAO/mcp. The documentation states support for Open Source, Enterprise, and Cloud. Use only HTTPS and a separate account; do not store tokens in repositories, chats, or shared files.
Configure the client according to the MCP documentation. Basic Auth uses Base64, not encryption. Do not put tokens in shared process arguments; protect the client configuration file and backups. unset does not delete a credential that the client has already written to disk.
AI telemetry may contain prompts, responses, identifiers, and retrieved documents. Define beforehand which attributes can leave the application, perform redaction when necessary, and align retention, LGPD, and access. Do not send secrets or API keys in logs or spans.
Operation, backup and update
- Monitor the service itself: CPU, RAM, I/O, free space, ingestion errors, query time, and bucket growth.
- Protect the metadata: on single node, local SQLite contains configurations, users, dashboards, and alerts; make consistent backup of
/var/lib/openobserveand the environment file, keeping secrets protected. - Test restoration: recovering only Parquet in the bucket does not automatically recreate users, dashboards, or rules.
- Update and rollback: make a consistent backup, validate the release, and install the binary side by side. Stop the service before swapping the link. Keeping the previous binary does not guarantee a downgrade: metadata migrations may require restoring the pre-update backup as well.
- Review retention:
ZO_COMPACT_DATA_RETENTION_DAYShas a pattern of 3650 days; define an explicit policy compatible with the bucket lifecycle rules.
Consistent backup and restore
On this single node, schedule a window, stop ingestion or ensure sufficient queues in the collectors, stop the service, and copy the entire data directory and configuration to protected storage. Preserve owner and permissions. Do not copy the SQLite alone while it is being modified.
In bucket mode, align the metadata recovery point with the objects and the backup policy. A local copy does not freeze the bucket. Restore first in an isolated network, with the same version; validate users, streams, dashboards, and queries before enabling ingestion. Record recovery time and maximum acceptable loss.
Common failures
- 502: check the service and response on loopback before changing nginx.
- 413: compare batch size with proxy and backend limits.
- 401/403: check credential, organization, and permissions; do not disable authentication.
- Bucket error: check endpoint, region, clock, key validity, and certificates. Do not disable TLS.
- Disk full: examine WAL, cache, and logs; do not manually delete internal files.
See also the essential systemd commands.
Final checklist
- Official binary installed and SHA-256 verified before execution.
- Service
openobserveactive, with writable data only by the dedicated account. - Ports 5080 and 5081 bound to loopback; interface available only in HTTPS via nginx.
- Root password and bucket credentials stored outside Git, chat, and unencrypted backups.
- Retention calculated with actual ingestion, not with a presumed compression ratio.
- Bucket write/read test and metadata restoration completed before production.
Want to evaluate another object backend with an S3 API? See RustFS on Linux: install via binary and Docker. S3 compatibility does not guarantee integration without adjustments: validate endpoint, region, authentication, and the operations used by OpenObserve in a lab before migrating data.
Official sources
- OpenObserve: binary downloads
- OpenObserve: self-hosted installation
- OpenObserve: systemd service
- OpenObserve: environment variables reference
- OpenObserve: local storage, S3, GCS, and MinIO
- OpenObserve: nginx as reverse proxy
- Certbot: nginx plugin and certificate renewal
- OpenObserve: MCP server
- OpenObserve: AI and LLM integrations
- Oracle Cloud: Amazon S3-compatible API